Pagination is how a site splits a long list, a category with hundreds of products, or a search-results page into a numbered series (page 1, page 2, page 3) instead of one enormous page. Handled well, it keeps crawl budget focused and lets every page in the series get indexed on its own terms. Handled badly, the most common mistake, canonicalising every page in the series back to page 1, quietly removes pages 2 onward from Google’s index entirely, along with every product or listing that only appears on them.
rel=”next”/”prev” Is Deprecated, Not a Ranking Signal
Google officially stopped using the rel="next" and rel="prev" link attributes as a pagination signal in March 2019. Many older guides still recommend adding them; they do no harm, but they do nothing for indexing or ranking either. Google’s current guidance is that paginated pages should be treated as standalone pages, each crawlable and indexable on its own, discoverable through normal internal linking rather than through a markup signal.
The Canonical Mistake That Deindexes Your Catalogue
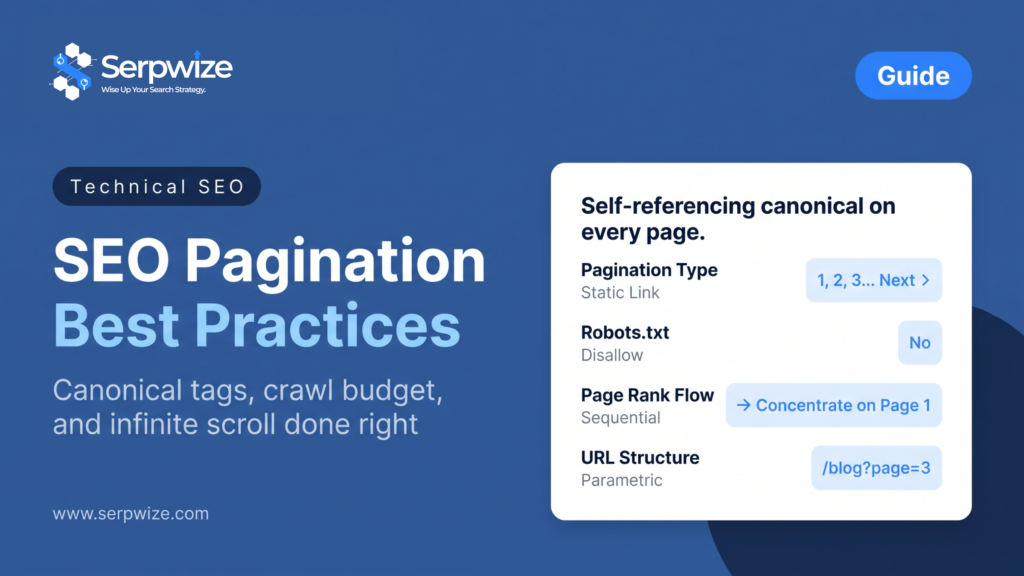
The single most damaging pagination mistake is setting the canonical tag on page 2, page 3, and beyond to point back to page 1. This tells Google those pages are duplicates of page 1 and should not be indexed separately, which means any product or listing that only appears on page 3 effectively disappears from search entirely. Each page in a paginated series should carry a self-referencing canonical tag, pointing to itself, not to page 1.
View-All Pages as an Alternative
If your catalogue or list is small enough to load acceptably as a single page, a “view all” version can consolidate ranking signal onto one URL and remove the pagination problem entirely. It only works when page-load performance stays acceptable; forcing hundreds of products onto one view-all page just to avoid pagination often creates a worse Core Web Vitals problem than the one it solves.
Infinite Scroll Needs a Pagination Fallback
Infinite scroll and “load more” buttons that fetch content via JavaScript without changing the URL are effectively invisible to crawlers, which do not click buttons or scroll indefinitely. The fix is to pair infinite scroll with real, crawlable paginated URLs underneath it, either through the History API updating the URL as the user scrolls, or a visible “page 2” link as a genuine fallback. A site that relies on infinite scroll alone for a large catalogue routinely finds most of that catalogue never gets crawled.
Crawl Budget at Scale
On a large ecommerce or listings site, an uncontrolled combination of pagination and filter parameters can generate far more URLs than actual products, and Google will not crawl all of them. This is exactly the kind of architecture problem that shows up as a symptom (pages not getting indexed) with a root cause several layers deeper (crawl budget burned on low-value paginated and filtered URL combinations). It is one of the first things we check in any ecommerce SEO or enterprise SEO audit, since fixing it usually recovers indexation for pages that were always there, just never reached.
Practical Pagination Checklist
- Self-referencing canonical tag on every page in the series, never all pointing to page 1
- Do not noindex paginated pages you want Google to use for reaching your products or listings
- Real, crawlable links to every page in the series, not just “next” buttons that need a click
- Infinite scroll paired with real paginated URLs underneath it, not JavaScript-only loading
- A “view all” alternative only where page weight and load speed stay genuinely acceptable
- Unique, non-thin content or listings on each page, not the same items reshuffled
Frequently asked questions
Should I still add rel=”next” and rel=”prev” tags?
It will not hurt, but Google has not used them as a signal since March 2019, so do not rely on them to fix an indexing problem. Focus on self-referencing canonicals and real internal linking instead.
Should paginated pages be noindexed?
Usually not. Noindexing page 2 onward removes any unique product or listing on those pages from search entirely, which is rarely the intended outcome. Reserve noindex for pages with genuinely no unique value, not for pagination by default.
Does infinite scroll hurt SEO?
Infinite scroll itself is not the problem; infinite scroll with no crawlable URL underneath it is. Pair it with real paginated URLs, updated via the History API or a visible fallback link, so crawlers can reach every page in the series.
How many products or items should each paginated page show?
There is no fixed rule; the right number balances page load speed against how many pages a user or crawler needs to click through. Fewer, well-optimised pages generally outperform many thin ones.
Serpwize fixes pagination and crawl-budget problems as part of every technical SEO audit. See our ecommerce SEO service.